Sealing and serving MiniMax H3
MiniMax H3 generates video with audio from text and images. kLLM seals an H3 partition
such as FL2VA as a whole pipeline and serves it with stock sglang serve. This page gives
the procedure, describes what is sealed, and reports the measured speed and fidelity.
Requirements
kLLM with the
sealandserveextras, and an SGLang build with diffusion support (sglang serve). The measurements below used SGLang 0.5.21.An NVIDIA GPU. The measurements used one A40 48 GB per pipeline with layer-wise offload.
Disk space for the pipeline and its sealed copy. FL2VA is 135 GB; sealing it took about 15 minutes on one A40, measured before weight locking was added.
H3 pipelines are served with SGLang only. They cannot be served with --engine vllm or
in client-keyed mode (--client).
Procedure
Download the partition:
$ hf download MiniMaxAI/MiniMax-H3 --include "FL2VA/*" --local-dir models/MiniMax-H3
Create a key if none exists, and seal the partition under
perm:$ kllm keygen $ kllm seal models/MiniMax-H3/FL2VA -o models/MiniMax-H3/FL2VA-sealed --transform perm
kllm sealrecognizes an H3 partition from the_class_namein itsmodel_index.json.Serve the sealed partition with the key. Arguments after
--go tosglang serveunchanged; the flags below enable layer-wise offload, which the measurements used on a 48 GB GPU:$ kllm serve models/MiniMax-H3/FL2VA-sealed --key --tp 1 --no-recipe -- \ --dit-layerwise-offload true --layerwise-offload-components text_encoder vae
Submit a generation request.
tools/h3_generate.pyposts one job to the server’s/v1/videosendpoint, waits for it, downloads the result and prints the elapsed time:$ python tools/h3_generate.py "A red fox trots through fresh snow in a birch forest at sunrise" \ --port 8000 --seed 7 --out fox.mp4
Its defaults are a 768-pixel short edge, a 16:9 aspect ratio, 4 seconds, the
t2vatask and the pipeline’s default number of steps;--short-edge,--aspect,--duration,--stepsand--taskchange them.
What kllm serve does
The engine reads the tokenizer from the pipeline directory, so kllm serve --key builds a
view of the sealed directory under /dev/shm, laid out as MiniMax-H3/<PARTITION>/:
every sealed file is a symbolic link, and the decrypted, permuted tokenizer files
(mode 0600) take the place of the public ones. It then runs:
sglang serve --model-path /dev/shm/kllm-tok-XXXX/MiniMax-H3 --num-gpus N \
    --host 0.0.0.0 --port 8000 [arguments after --] --model-variant fl2va
--tp sets --num-gpus. Recipes are never applied to H3. For another launcher,
kllm unlock models/MiniMax-H3/FL2VA-sealed builds the same view and prints the model
directory to pass to sglang serve.
Warning
The view, including the decrypted tokenizer, is not removed when the server exits.
Outside a confidential VM it lies in host memory and offers no protection from the host.
Remove /dev/shm/kllm-tok-* directories that are no longer in use.
What is sealed
kllm seal seals the whole chain of the pipeline:
Text encoder. The Qwen3-VL language model takes the LLM transforms of the selected transform; the vision mergers write into its residual stream, and the embedding is under the vocabulary permutation.
Diffusion transformer. AdaLN modulation, gates and the residual stream are under one signed permutation, whatever the selected transform, because AdaLN scales channels one by one and a dense basis cannot pass through it. Heads, RoPE pairs, the 32 pass-through head dimensions and the MLP are transformed as in an LLM;
condition_projreads the text encoder’s basis.Latent interfaces. The 24 video and 32 audio latent channels are permuted. The patch projections and output heads of the DiT, the outputs of the VAE encoders, the inputs of the decoders and the per-channel latent statistics absorb the permutation. The VAE interiors are not transformed.
Tokenizers. The tokenizer files of
tokenizer/,processor/andtext_encoder/are permuted and encrypted intrusted.kllm.
The pipeline keeps its layout and file names; kllm.json records the scheme, transform,
key fingerprint and partition. The test suite checks the sealed DiT against the plain one
in float64 to 1e-9 under both transforms (tests/test_h3.py).
Results
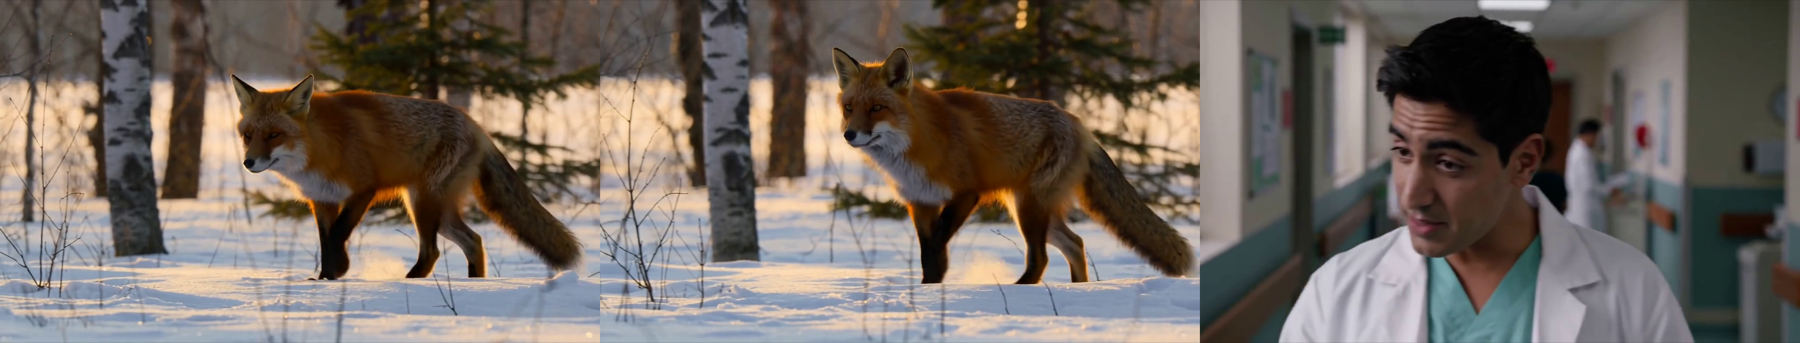
Same prompt, seed 7, 768p, 4 s, 49 steps on one A40 with layer-wise offload (SGLang
0.5.21). Left: plain H3. Middle: sealed with perm, started from the same noise
(permuted into the sealed latent basis). Right: the sealed files without the key, run with
the public tokenizer.
A wrong key does not reach the stage shown on the right: kllm serve refuses a key whose
fingerprint does not match, and the tokenizer cannot be decrypted without the right key.
End-to-end time, plain and sealed under perm, each pair run at the same time on two
GPUs of the same host:
Steps |
plain (s) |
sealed (s) |
|---|---|---|
49 |
1287 / 1507 |
1262 / 1512 |
8 |
220.4 |
220.4 |
2 |
110.3 |
110.3 |
The two 49-step runs differ in what else the host was running. Denoising took 24.80 s (plain) and 24.91 s (sealed) per step.
H3 is deterministic: plain H3 run twice gives byte-identical video and audio. Any change of bf16 rounding, however, grows over the denoising steps. Relative L2 error of the final latents against plain (video / audio):
after 1 step |
after 7 steps |
after 48 steps |
|
|---|---|---|---|
Plain with PyTorch SDPA instead of FlashAttention |
1.7% / 2.5% |
20.3% / 13.6% |
45.8% / 19.9% |
Sealed |
1.5% / 2.5% |
16.4% / 10.8% |
42.8% / 10.8% |
Sealed |
1.8% / 6.9% |
30.7% / 47.1% |
not run |
Under perm the drift stayed within that of a mathematically identical kernel swap at
every measured step count. After 49 steps the video shows the same scene, composition,
lighting and subject in a slightly different pose: frame PSNR against plain was 18.1 dB for
sealed perm and 17.3 dB for plain with SDPA, against 10.5 dB for the sealed files run
with the public tokenizer. orth also re-rounds the rotated weights of the text encoder,
to which the audio stream is most sensitive; perm is the recommended transform for H3.
To reproduce these results, use benchmarks/h3.sh (see Benchmarking plain and sealed serving). To run the
DiT on INT8 kernels, see Running the H3 diffusion transformer on INT8 kernels.
Security notes
FL2VA’s weights are public, so sealing does not protect the weights. It keeps the tokenizer secret, and the prompt reaches the GPU as permuted token ids.
The VAE decoders run on the GPU in the clear, so the generated video and audio are in GPU memory in the clear. During denoising the latents are under a fixed permutation of channels, which statistics would undo.
The general limits in Claims apply.
See also
Running the H3 diffusion transformer on INT8 kernels for the optional INT8 kernels.
Examples for the end-to-end H3 example.
Attacks for the measurements on H3 outputs.